Verifiable Hidden Dynamics Play: Generating Agentic RL Environments from Solved Mechanisms
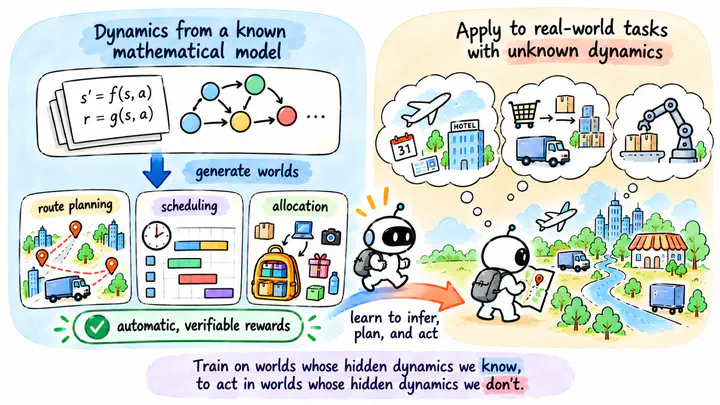 From a known mechanism to verifiable training worlds and transfer.
Abstract
VHD-Play generates agentic reinforcement-learning environments from solved mathematical mechanisms. The executable dynamics and scoring reference come from the same solved model, providing verifiable rewards by construction. The pipeline produces 3,300 environments, and training Qwen3.6-35B-A3B on three mechanism families raises its mean agentic score from 0.204 to 0.815. Gains transfer to eight unseen mechanism families and external benchmarks.
VHD-Play starts from a solved mathematical mechanism, then renders its decision process as stateful tools. Because the environment dynamics and outcome evaluator are inherited from the same source, each generated world has a dependable reward without trajectory annotation.
Train on worlds whose hidden dynamics we know, to act in worlds whose hidden dynamics we do not.
The generated substrate scales to 3,300 environments at a cost of a few cents each. Training transfers beyond the three training families to eight unseen mechanism families and external function-calling, travel-planning, and long-horizon e-commerce tasks.
Xinjie Shen 沈鑫杰
PhD Student @ Georgia Tech
I study how to train capable agents and make them safe and reliable in open-ended environments.